Build a Zero-Dependency List Virtualization Hook in React
You render 10,000 rows. The page freezes for a moment, the scrollbar stutters, and the browser tab's memory climbs. Nothing is wrong with your data fetching or your component logic. The browser is simply being asked to build, style, lay out and keep alive far more elements than any user can see at once.
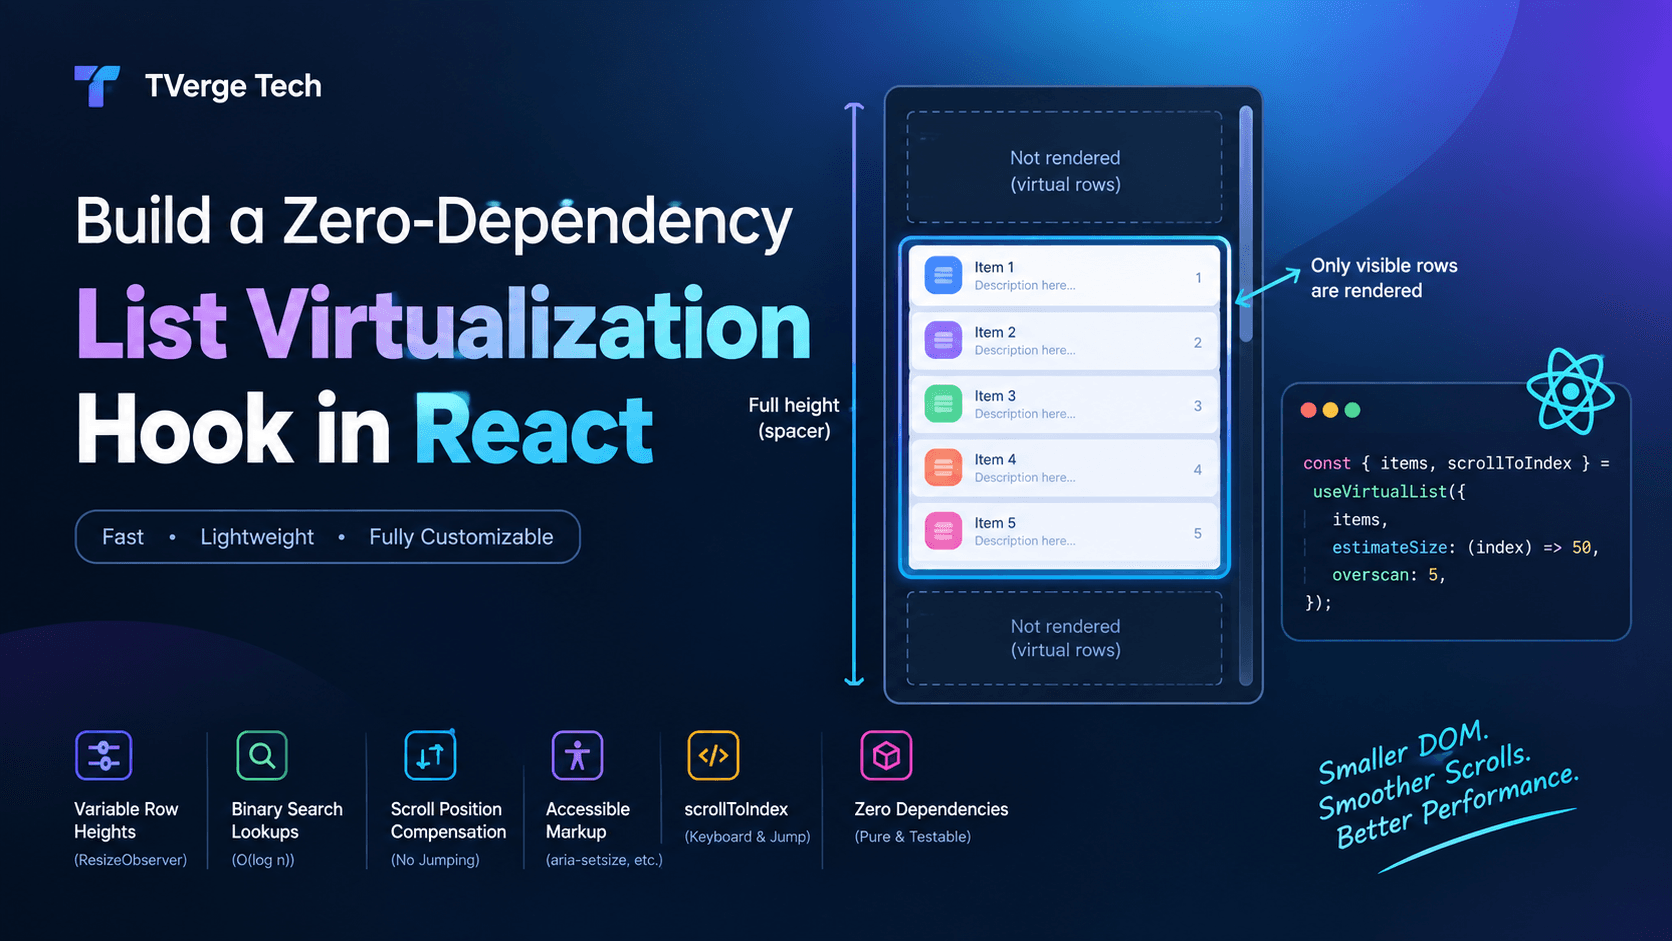
List virtualization (also called windowing) fixes this by rendering only the rows near the viewport and faking the rest of the scroll height. The DOM stays small whether you have 500 rows or 500,000.
Libraries such as TanStack Virtual and react-window do this well. But building the mechanism once, from scratch, teaches you what those libraries are doing, helps you debug them, and gives you a tiny hook you fully control. In this guide we build a zero-dependency virtualization hook in React and TypeScript with:
Variable row heights, measured automatically with ResizeObserver
Binary-search lookups over a Float64Array, so finding the first visible row is O(log n)
Scroll position compensation, so late-measured rows don't make the list jump
By the end you'll also know when not to virtualize, which matters just as much.
Why large lists get slow
Rendering a list is not just "creating elements." For every row the browser must create DOM nodes, resolve styles, compute layout and paint. Frameworks add their own work on top: React must create, reconcile and hold a fiber for each component. React's guide to rendering lists shows how the default approach maps every array item to an element, which is exactly why very large arrays become expensive.
The cost isn't limited to the first render. Per the web.dev guidance on DOM size and interactivity, a large DOM can increase the cost of style recalculation and layout, which can slow down responses to user input. That affects Interaction to Next Paint (INP), one of the Core Web Vitals. Chrome's Lighthouse also flags oversized DOM trees in its DOM size audit, which warns once a page grows past roughly 800 nodes and fails past roughly 1,400.
A table with 5,000 rows and 8 cells each is already 40,000+ elements before you count wrappers, icons and buttons. Virtualization attacks the root cause: fewer nodes, less work every frame.
How windowing works
Virtualization rests on three ideas:
A tall, empty spacer. Make the scroll area as tall as the full list would be, so the scrollbar behaves honestly. The scroll container uses the standard overflow property.
A visible window. From scrollTop and the viewport height, work out which row indexes are on screen.
Absolute positioning. Render only those rows (plus a small buffer called overscan) and place each one at its computed offset using position: absolute and a translateY transform.
With fixed-height rows the math is trivial: startIndex = floor(scrollTop / rowHeight). Real lists rarely behave like that. Chat messages, comments, cards and wrapped text all have different heights. So we need a structure that answers two questions quickly:
Where does row i start? (a prefix sum of heights)
Which row contains pixel offset y? (a binary search over those prefix sums)
That structure is the heart of the hook.
When you should not virtualize
Virtualization adds complexity and has real trade-offs. Skip it when:
The list is small. A few hundred simple rows is usually fine as plain DOM.
Users need browser find-in-page. Ctrl/Cmd+F can't find rows that aren't in the DOM.
The content must be crawlable. Search engines index what's in the rendered DOM. If listing content matters for SEO, use real pagination. Google's guidance on pagination and incremental page loading covers the details.
A CSS-only option is enough. The content-visibility property can let the browser skip rendering work for off-screen content. It keeps the nodes in the DOM, so it helps with paint and layout cost but doesn't reduce node count or memory the way true virtualization does. web.dev's article on content-visibility explains the trade-offs in depth.
Measure first. If a profile shows rendering isn't your bottleneck, don't add machinery.
Adjust scrollTop when rows above the viewport change size
Accessible
ARIA position attributes, focusable scroller
Testable
Pure SizeIndex class with no DOM dependency
Step 1: The size index (pure logic)
We keep the math in a plain class so it can be unit-tested without a browser. It stores measured sizes by key (not index) in a JavaScript Map, so rows keep their measured height when data is prepended or reordered. It stores offsets in a typed Float64Array and recomputes them lazily, starting only from the first changed row.
// size-index.ts
import type { Key } from "react";

export const indexKey = (i: number): Key => i;

export class SizeIndex {
  private sizes = new Map<Key, number>();
  private offsets = new Float64Array(1); // offsets[i] = start of item i
  private count = 0;
  private estimate = 0;
  private resetKey: unknown = undefined;
  private dirtyFrom = 0; // offsets[0..dirtyFrom] are valid
  private getKey: (i: number) => Key = indexKey;

  get length(): number {
    return this.count;
  }

  configure(
    count: number,
    estimate: number,
    getKey: (i: number) => Key,
    resetKey?: unknown
  ): void {
    this.getKey = getKey;

    if (count !== this.count) {
      this.offsets = new Float64Array(count + 1);
      this.count = count;
      this.dirtyFrom = 0; // prepends shift everything, so rebuild
    }
    if (estimate !== this.estimate || resetKey !== this.resetKey) {
      this.estimate = estimate;
      this.resetKey = resetKey;
      this.dirtyFrom = 0;
    }
  }

  /** Record a measured size. Returns the change versus the previous size. */
  setSize(index: number, size: number): number {
    const key = this.getKey(index);
    const prev = this.sizes.get(key);
    if (prev === size) return 0;
    this.sizes.set(key, size);
    if (index < this.dirtyFrom) this.dirtyFrom = index;
    return size - (prev ?? this.estimate);
  }

  sizeOf(index: number): number {
    return this.sizes.get(this.getKey(index)) ?? this.estimate;
  }

  start(index: number): number {
    this.ensure();
    return this.offsets[index];
  }

  total(): number {
    this.ensure();
    return this.offsets[this.count];
  }

  /** Largest i such that start(i) <= offset (binary search). */
  indexAt(offset: number): number {
    this.ensure();
    let lo = 0;
    let hi = this.count - 1;
    while (lo < hi) {
      const mid = (lo + hi + 1) >>> 1;
      if (this.offsets[mid] <= offset) lo = mid;
      else hi = mid - 1;
    }
    return lo;
  }

  private ensure(): void {
    if (this.dirtyFrom >= this.count) return;
    let acc = this.offsets[this.dirtyFrom];
    for (let i = this.dirtyFrom; i < this.count; i++) {
      this.offsets[i] = acc;
      acc += this.sizes.get(this.getKey(i)) ?? this.estimate;
    }
    this.offsets[this.count] = acc;
    this.dirtyFrom = this.count;
  }
}
Three details are worth noting:
Estimates first, measurements later. Unmeasured rows use estimate. As rows scroll into view and get measured, offsets are corrected.
Lazy recomputation. When row 900 changes size, offsets before 900 are still valid, so the loop restarts at 900, not 0.
Known limit. Updating the tail is O(n). For millions of rows, a Fenwick (binary indexed) tree gives O(log n) updates and lookups. For typical lists up to the low hundreds of thousands, the linear tail pass is usually acceptable, but profile your own data.
Step 2: The hook
The hook connects the index to the browser. It uses React's useState, useReducer, useRef and useLayoutEffect to track the scroll container's scrollTop and height, compute the visible range, observe rendered rows, and compensate for size changes above the viewport.
Two browser details matter here. The scroll event is dispatched at most once per rendered frame, so we read scrollTop directly in the handler without extra throttling. We also register it as a passive listener, which tells the browser we won't call preventDefault() and lets scrolling stay smooth.
// use-virtual-list.ts
import {
  useCallback,
  useLayoutEffect,
  useReducer,
  useRef,
  useState,
  type Key,
} from "react";
import { SizeIndex, indexKey } from "./size-index";

export interface VirtualItem {
  index: number;
  key: Key;
  start: number;
  size: number;
}

export interface UseVirtualListOptions {
  count: number;
  /** Height used for rows that haven't been measured yet. */
  estimateSize: number;
  /** Extra rows rendered above and below the viewport. Default 4. */
  overscan?: number;
  /** Stable key per row. Strongly recommended for dynamic data. */
  getKey?: (index: number) => Key;
  /** Change this when row order changes without the count changing. */
  resetKey?: unknown;
}

export interface UseVirtualListResult {
  scrollRef: (el: HTMLElement | null) => void;
  virtualItems: VirtualItem[];
  totalSize: number;
  scrollToIndex: (
    index: number,
    align?: "start" | "center" | "end"
  ) => void;
}

export function useVirtualList(
  options: UseVirtualListOptions
): UseVirtualListResult {
  const {
    count,
    estimateSize,
    overscan = 4,
    getKey = indexKey,
    resetKey,
  } = options;

  // A lazily-initialised cache. See the purity note below.
  const indexRef = useRef<SizeIndex | null>(null);
  if (indexRef.current === null) indexRef.current = new SizeIndex();
  const sizeIndex = indexRef.current;
  sizeIndex.configure(count, estimateSize, getKey, resetKey);

  const [scrollEl, setScrollEl] = useState<HTMLElement | null>(null);
  const [viewport, setViewport] = useState({ top: 0, height: 0 });
  const [, rerender] = useReducer((n: number) => n + 1, 0);

  const observerRef = useRef<ResizeObserver | null>(null);
  const observed = useRef(new Set<HTMLElement>());

  // 1) Track scroll position and viewport size.
  useLayoutEffect(() => {
    if (!scrollEl) return;

    const read = () => {
      const top = scrollEl.scrollTop;
      const height = scrollEl.clientHeight;
      setViewport((v) =>
        v.top === top && v.height === height ? v : { top, height }
      );
    };

    read();
    scrollEl.addEventListener("scroll", read, { passive: true });
    const ro = new ResizeObserver(read);
    ro.observe(scrollEl);

    return () => {
      scrollEl.removeEventListener("scroll", read);
      ro.disconnect();
    };
  }, [scrollEl]);

  // 2) Create the observer that measures rendered rows.
  useLayoutEffect(() => {
    if (!scrollEl) return;
    const seen = observed.current;

    const ro = new ResizeObserver((entries) => {
      // Read positions BEFORE applying any change in this batch.
      const updates = entries.flatMap((entry) => {
        const el = entry.target as HTMLElement;
        const index = Number(el.dataset.index); // data-index attribute
        if (!Number.isInteger(index) || index >= sizeIndex.length) return [];
        // borderBoxSize: https://developer.mozilla.org/en-US/docs/Web/API/ResizeObserverEntry/borderBoxSize
        const size =
          entry.borderBoxSize?.[0]?.blockSize ??
          el.getBoundingClientRect().height;
        return [{ index, size, start: sizeIndex.start(index) }];
      });

      let changed = false;
      let compensation = 0;
      for (const { index, size, start } of updates) {
        const delta = sizeIndex.setSize(index, size);
        if (delta === 0) continue;
        changed = true;
        // A row above the viewport changed size: shift scrollTop by the
        // same amount so visible content doesn't jump.
        if (start < scrollEl.scrollTop) compensation += delta;
      }

      if (compensation !== 0) scrollEl.scrollTop += compensation;
      if (changed) rerender();
    });

    observerRef.current = ro;
    return () => {
      ro.disconnect();
      seen.clear();
      observerRef.current = null;
    };
  }, [scrollEl, sizeIndex]);

  // 3) After every render, sync which row elements are observed.
  useLayoutEffect(() => {
    const ro = observerRef.current;
    if (!scrollEl || !ro) return;
    const seen = observed.current;
    const live = new Set(
      scrollEl.querySelectorAll<HTMLElement>("[data-index]")
    );
    for (const el of seen) {
      if (!live.has(el)) {
        ro.unobserve(el);
        seen.delete(el);
      }
    }
    for (const el of live) {
      if (!seen.has(el)) {
        ro.observe(el);
        seen.add(el);
      }
    }
  });

  // Compute the visible range.
  const virtualItems: VirtualItem[] = [];
  const totalSize = sizeIndex.total();
  if (count > 0 && viewport.height > 0) {
    const first = sizeIndex.indexAt(viewport.top);
    const last = sizeIndex.indexAt(viewport.top + viewport.height);
    const from = Math.max(0, first - overscan);
    const to = Math.min(count - 1, last + overscan);
    for (let i = from; i <= to; i++) {
      virtualItems.push({
        index: i,
        key: getKey(i),
        start: sizeIndex.start(i),
        size: sizeIndex.sizeOf(i),
      });
    }
  }

  const scrollToIndex = useCallback(
    (index: number, align: "start" | "center" | "end" = "start") => {
      if (!scrollEl || count === 0) return;
      const i = Math.min(Math.max(index, 0), count - 1);

      const go = () => {
        const start = sizeIndex.start(i);
        const size = sizeIndex.sizeOf(i);
        const h = scrollEl.clientHeight;
        const target =
          align === "start"
            ? start
            : align === "end"
            ? start + size - h
            : start + size / 2 - h / 2;
        scrollEl.scrollTop = Math.max(0, target);
      };

      go();
      // Estimated rows get measured after the first jump, so settle once.
      requestAnimationFrame(go);
    },
    [scrollEl, count, sizeIndex]
  );

  return { scrollRef: setScrollEl, virtualItems, totalSize, scrollToIndex };
}
A note on render purity
React asks components to be pure (see Keeping Components Pure), and the useRef reference advises against reading or writing ref.current during rendering, except for lazy initialization. Our configure() call updates a derived cache during render. It is deterministic and idempotent: calling it twice with the same inputs gives the same result, so Strict Mode's double render and discarded concurrent renders are harmless. Measured sizes change only inside the ResizeObserver callback, never during render.
If you want strict purity, replace the cache with useMemo and a full offset rebuild on every size change. It's simpler, but O(n) per measurement batch.
Why useLayoutEffect?
The initial viewport read and the scroll compensation must run before the browser paints, or users see a flash of empty content or a visible jump. The useLayoutEffect reference describes this use case: measuring layout and re-rendering synchronously before paint. It also warns that it blocks painting, so use it sparingly. For most effects, React's guide on synchronizing with Effects explains when plain useEffect is the better choice.
How the measurement works
ResizeObserver notifies us whenever an observed element's size changes, including once when observation starts, which gives us the first measurement of every newly rendered row. We read the borderBoxSize so padding and borders are included, with a getBoundingClientRect() fallback for older engines. Row indexes travel on the element through a data-* attribute, read back through the dataset property.
Step 3: The list component
The component stays small. Row content is memoized with React's memo, so the parent re-rendering on each scroll update doesn't force every visible row to re-render.
data-index is required. The measuring observer reads it to know which row changed.
overflow-anchor: none. Browsers have their own scroll anchoring. Turn it off here so it doesn't fight our compensation. See MDN's overflow-anchor and scroll anchoring guide.
Use padding, not margins, on measured rows.ResizeObserver reports the border box, which excludes margins, so margins would silently break offsets. The CSS box model explains why. Spacing belongs inside the measured element.
Stable keys. React's documentation on keeping list items in order with key recommends database IDs over array indexes whenever rows can be inserted, removed or reordered. Need unique IDs for test data? The Bulk UUID Generator can produce thousands at once.
Accessibility: don't let virtualization break screen readers
When most rows aren't in the DOM, assistive technology can't know how long the list really is. The fix is to tell it:
Use list semantics. MDN documents the list and listitem roles we apply to the container and rows.
Declare size and position.aria-setsize gives the total number of items and aria-posinset gives each item's 1-based position. MDN describes this as the right tool when only part of a set is in the DOM.
Make the scroll region keyboard reachable.tabindex="0" plus an accessible name (aria-label) lets keyboard users focus the container and scroll with arrow keys, Page Up/Down and Home/End.
Manage focus deliberately. If a focused row scrolls out and unmounts, focus is lost. For interactive rows (selectable lists, grids), track the active index in state and call scrollToIndex when arrow keys move it, instead of relying on DOM focus alone.
Choose semantics that match the content. The W3C ARIA Authoring Practices Guide has patterns for feeds and grids that are worth reading before you ship a complex widget.
Performance tuning that actually matters
Overscan. A buffer of a few rows prevents blank flashes during fast scrolling. Too little shows blank gaps. Too much makes the DOM larger and the benefit smaller. Start at 4 to 8 and tune with real devices.
Memoize row content. Our parent re-renders whenever the visible range changes. A memo boundary around row content (as above) keeps unchanged rows from re-rendering. Pass stable props, not freshly created objects or inline callbacks. React's memo reference covers the comparison rules, and useCallback helps keep function props stable.
Keep rows cheap. Virtualization limits how many rows exist, not how expensive each one is. Avoid heavy per-row layout, large images without dimensions, and effects that run on mount for every row.
Reserve space for images. An image that loads after the row is measured changes the row's height. ResizeObserver will correct it, but each correction triggers a re-render. Setting width and height attributes or the CSS aspect-ratio property avoids most of this. web.dev's guide to optimizing Cumulative Layout Shift explains the same principle for page-level stability.
Estimate well. The closer estimateSize is to the real average, the fewer corrections happen and the more accurate the scrollbar feels.
Scaling limits to know about
Maximum element height. Browsers cap how tall an element can be, in the tens of millions of pixels, with different limits per engine. At 56 px per row, you may hit that wall somewhere in the hundreds of thousands of rows. If you do, the usual answers are to page or chunk the dataset, or to map scroll position through a scale factor. Most real products are better served by server-side pagination, search and filtering long before this point.
Memory for measurements. The sizes map grows as users scroll. For very long sessions on huge lists, you can evict entries far from the viewport. Chrome's guide to fixing memory problems shows how to confirm whether this is an issue for your data.
Prepending items. When older items load at the top (chat history), the count changes and offsets are rebuilt. Because sizes are keyed by item ID, existing rows keep their measurements. Preserve the user's position by adjusting scrollTop by the added height of the new items.
Streaming and append-heavy lists
Live logs, chat transcripts and streaming output append rows continuously. Two points apply:
Batch updates. Appending on every incoming token or event forces constant re-renders. Batching updates per animation frame with requestAnimationFrame keeps the UI responsive, and React's own automatic batching groups state updates for you. Our guide to optimizing LLM streaming payloads in Python backends covers batching and backpressure on the server side, which pairs well with a virtualized front end.
Respect user intent. Auto-scroll to the bottom only when the user is already near the bottom. Otherwise you'll yank them away from what they were reading.
Server rendering and SEO
Virtualized content exists only after client-side code runs, and only for the rows near the viewport. For anything you want indexed, don't rely on virtualization alone. Google's JavaScript SEO basics explain how rendering works for Search, and its guidance on creating helpful, people-first content is a good test for any listing page. A safe pattern is:
Render the first page of results as normal HTML on the server.
Provide real paginated URLs for the rest, with crawlable links.
Enable virtualization for the interactive experience (dashboards, logs, internal tools) where indexing doesn't matter.
The hook uses state, effects and browser APIs, so in frameworks with server components it must live in a Client Component. React's 'use client' directive reference explains the boundary: fetch data on the server and pass it down as props.
If you're also debugging mismatches between server and client output, our guide to fixing hydration mismatch errors in Next.js App Router is a useful companion, since virtualized lists that depend on measured browser size are a classic source of them. React documents the underlying rules in its hydrateRoot reference. Render the virtualized window only after mount.
Testing the hook
jsdom doesn't do layout, so don't test measurement there. Test the pure SizeIndex with Vitest, then verify browser behavior with a real-browser runner such as Playwright or Vitest Browser Mode.
import { describe, expect, it } from "vitest";
import { SizeIndex } from "./size-index";

describe("SizeIndex", () => {
  const make = () => {
    const idx = new SizeIndex();
    idx.configure(1000, 50, (i) => i);
    return idx;
  };

  it("uses the estimate until rows are measured", () => {
    expect(make().total()).toBe(50_000);
  });

  it("shifts later offsets when a row is measured", () => {
    const idx = make();
    idx.setSize(10, 150);
    expect(idx.start(11)).toBe(650);
    expect(idx.total()).toBe(50_100);
  });

  it("finds the row containing an offset", () => {
    const idx = make();
    idx.setSize(10, 150);
    expect(idx.indexAt(649)).toBe(10);
    expect(idx.indexAt(650)).toBe(11);
  });

  it("keeps measurements by key when data is prepended", () => {
    const idx = new SizeIndex();
    const ids = ["a", "b", "c"];
    idx.configure(3, 50, (i) => ids[i]);
    idx.setSize(0, 100); // "a" is 100px
    ids.unshift("z");
    idx.configure(4, 50, (i) => ids[i]);
    expect(idx.sizeOf(1)).toBe(100); // "a" is now index 1
  });
});
Add browser-level tests for the behavior unit tests can't cover: the rendered node count stays bounded while scrolling, no blank gap appears during fast scrolling, and scrollToIndex lands on the right row.
How to measure the improvement honestly
Don't trust a hunch, and don't copy someone else's benchmark numbers. Your rows, devices and data differ. Use a repeatable method:
Count DOM nodes. Run document.querySelectorAll("*").length in the console before and after.
Profile scrolling. In Chrome DevTools' Performance panel, record a scroll through the list and look for long tasks and dropped frames. See Chrome's documentation on analyzing runtime performance.
Check memory. Compare heap snapshots with and without virtualization, following Chrome's memory problems guide.
Throttle. Use CPU throttling and test on a mid-range phone, not only a developer laptop.
Test with real data. Include your longest strings, tallest images and worst-case rows.
Run Lighthouse. Look at the DOM size audit mentioned earlier, and track INP in the field.
Record before and after numbers for your own app. They're the only ones that matter for your decision.
Common pitfalls
Symptom
Likely cause
Fix
Content jumps while scrolling up
Rows above the viewport measured late
Keep scroll compensation; improve estimateSize
Gaps or blank flashes
Overscan too low or rows too slow to render
Increase overscan; simplify row content
Rows overlap or leave gaps
Margins on measured elements
Use padding inside the measured wrapper (box model)
A hand-built hook is a good fit when you want a small, auditable core, you have one list shape, and you're comfortable owning the edge cases. Reach for a maintained library when you need:
Two-dimensional grid virtualization
Sticky headers or sections
Horizontal and window-level scrolling
Smooth-scroll animation and complex dynamic measurement
Long-term maintenance by a community
TanStack Virtual offers a headless useVirtualizer hook, and react-window provides lightweight list and grid components. Having built the mechanism yourself, you'll configure either one far more confidently.
If your rows come from an API, a typed model helps catch mistakes early. The JSON to TypeScript Converter can generate interfaces from a sample response, and the JSON Formatter & Validator helps inspect payloads while you debug. The TypeScript handbook is the official reference for the generics and interfaces used throughout this guide.
Frequently asked questions
What is list virtualization?
List virtualization, or windowing, is a rendering technique where only the items visible in the viewport (plus a small buffer) are in the DOM. The scroll height is simulated so the list still behaves like the full list.
How many rows justify virtualization?
There's no universal number. It depends on row complexity and target devices. Profile your actual list. If scrolling or interaction stutters, or the DOM is very large, virtualization is worth considering. Lighthouse's DOM size audit gives a useful rough signal.
Does virtualization hurt SEO?
It can, if important content only appears in unrendered rows. Use server-rendered content and crawlable pagination for anything that should be indexed, and reserve virtualization for interactive views. See Google's pagination guidance.
Why measure rows instead of assuming a fixed height?
Real content wraps, loads images and changes with viewport width. Measuring with ResizeObserver keeps offsets accurate without hard-coding heights.
Can I use this with React Server Components?
The hook uses state, effects and browser APIs, so it must live in a Client Component marked with 'use client'. Fetch data on the server and pass it as props.
Is it safe to write to a ref-based cache during render?
It's a deliberate trade-off. The cache is deterministic and derived from inputs, so repeated renders are harmless. React's purity guidance describes the stricter alternative, at the cost of more recomputation.
Conclusion
A virtualization hook is conceptually small: a prefix-sum index, a binary search, a ResizeObserver and careful scroll compensation. The real work is in the edges, which are variable heights, scroll jumps, accessibility, keyboard focus, SEO and testing.
Start by measuring whether your list actually needs virtualization. If it does, the hook in this guide gives you a dependency-free foundation you can read in one sitting and adapt to your data. Whether you keep it or move to a library later, you now understand exactly what's happening inside the scroll container.