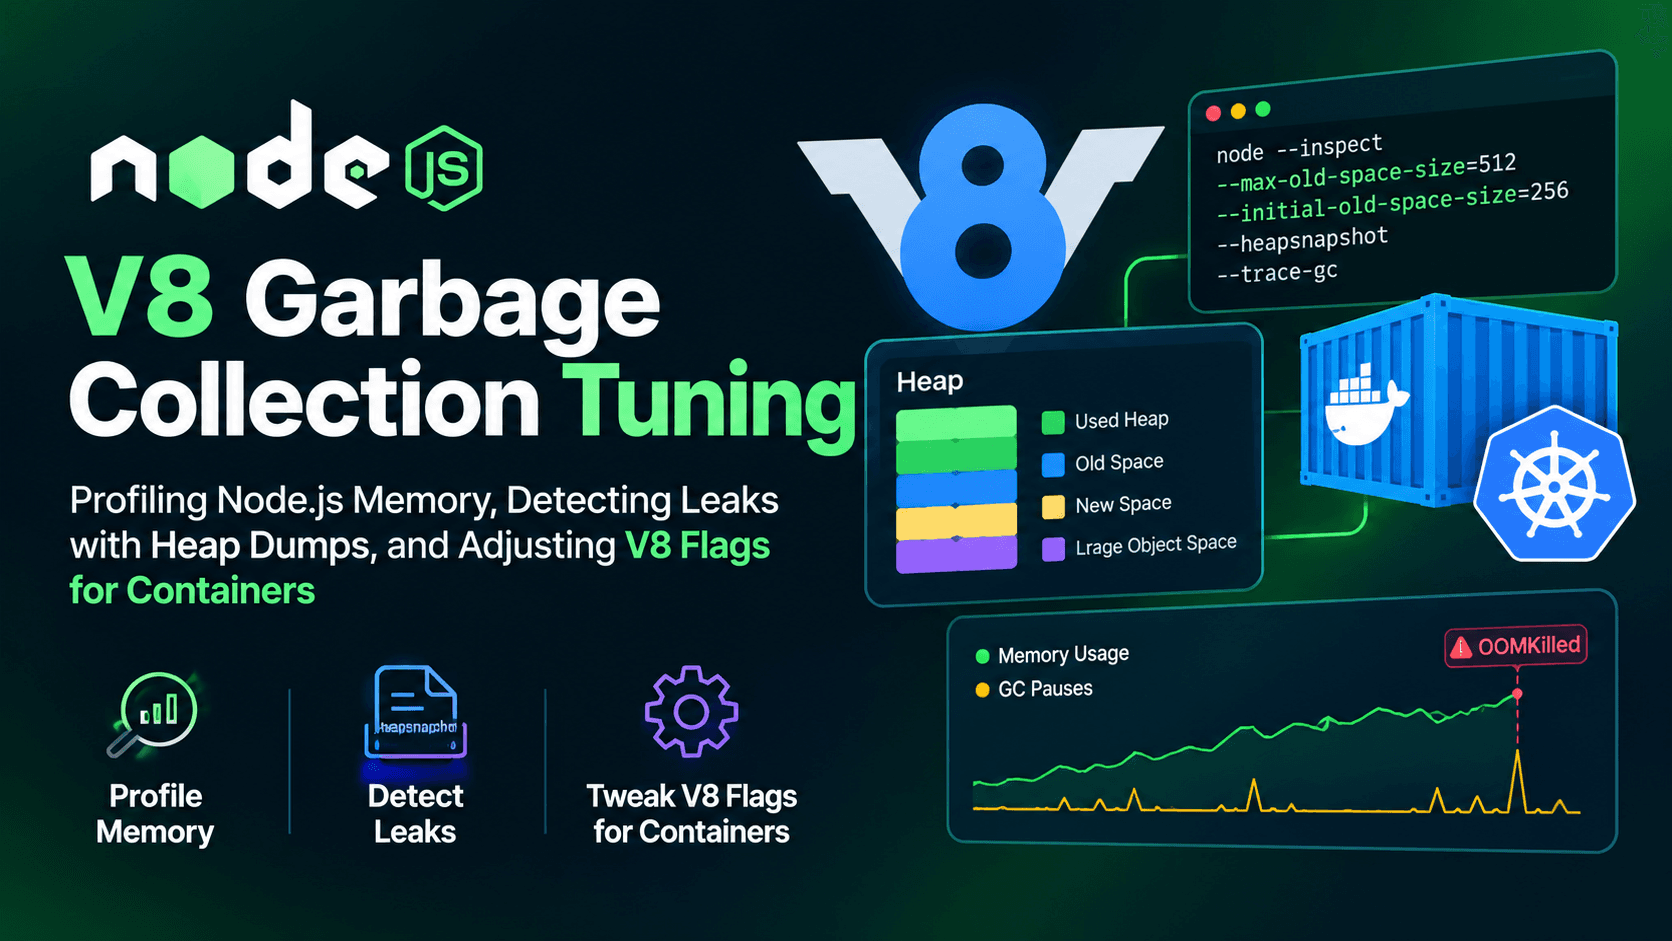
V8 Garbage Collection Tuning: Profiling Node.js Memory, Detecting Leaks with Heap Dumps, and Adjusting V8 Flags for Containers
Node.js applications that run smoothly on a developer's laptop can behave very differently once they're deployed inside a Docker container or a Kubernetes pod. Memory usage creeps up for no obvious reason, the process gets OOMKilled at 2 a.m., or garbage collection pauses start showing up as latency spikes in your dashboards. In almost every case, the root cause traces back to one thing: the V8 JavaScript engine's memory model was never designed with a hard container memory ceiling in mind, and left unconfigured, it will happily try to use far more (or, in some setups, far less) than what your container actually has.
This guide walks through how V8's garbage collector actually manages memory, how to profile a running Node.js process to see what's really happening inside the heap, how to pull and read heap snapshots to hunt down leaks, and how to set V8 flags correctly for containerized runtimes so your service stays predictable under load.
How V8 Manages Memory (The Short Version You Actually Need)
Before touching any flags, it helps to understand what V8 is doing under the hood. V8 splits managed memory into a few key regions, and most of what you'll tune revolves around two of them.
New Space (Young Generation). Every object starts here. Most objects — a temporary variable, a short-lived closure, a request-scoped object — die almost immediately. V8 uses a fast "Scavenge" collector for this space because it's small and collection is cheap and frequent.
Old Space (Old Generation). Objects that survive a couple of Scavenge cycles get promoted here. This is where long-lived data lives: caches, singletons, session state, anything referenced from a module-level variable. Old Space is collected with a slower Mark-and-Sweep (and Mark-Compact) algorithm, and it's the space that --max-old-space-size controls.
This design is based on the "generational hypothesis" — the observation that most objects die young, so it's efficient to collect the young generation frequently and cheaply while collecting the old generation less often but more thoroughly. When Old Space usage approaches its configured ceiling, V8 spends increasingly more CPU time trying to reclaim memory before it resorts to a full, stop-the-world collection. If live objects still exceed the limit after that, the process crashes with a fatal JavaScript heap out of memory error rather than being allowed to grow indefinitely.
That last point matters enormously in a container: V8's heap limit and your container's memory limit are two separate numbers, and if you don't align them, you'll see one of two failure modes — either V8 crashes with an OOM error well before the container limit is reached, or V8 grows past what the container allows and the kernel's OOM killer terminates the whole container abruptly, with no stack trace at all.
Step 1: Profile the Heap Before You Touch Any Flags
Tuning flags without first understanding actual memory behavior is guesswork. Start by measuring.
Baseline memory with the built-in v8 module
Node.js ships a node:v8 module that exposes heap statistics without any external tooling:
import v8 from 'node:v8';

const stats = v8.getHeapStatistics();
console.log({
  totalHeapSizeMB: (stats.total_heap_size / 1024 / 1024).toFixed(1),
  usedHeapSizeMB: (stats.used_heap_size / 1024 / 1024).toFixed(1),
  heapSizeLimitMB: (stats.heap_size_limit / 1024 / 1024).toFixed(1),
});
Log this on an interval (or expose it on a metrics/health endpoint) and watch the trend over hours, not seconds. A heap that grows and then plateaus after GC is healthy. A heap that grows in a straight line and never comes back down after a full GC cycle is the classic signature of a leak.
Watching it happen in real time
For interactive profiling, start Node with the inspector enabled:
node --inspect index.js
Then open chrome://inspect in Chrome, click "inspect" under your Node target, and switch to the Memory panel. From here you can record allocation timelines and take snapshots against a live process — the same workflow browser developers use to debug front-end memory issues, just pointed at your server process instead of a web page.
Correlate with container-level metrics
Process-level heap stats only tell part of the story. You also want to know what the container's cgroup thinks total memory usage is (RSS, cache, etc.), since V8's heap is only one part of a Node process's total footprint — native addons, Buffers, and the C++ side of the engine all consume memory outside the tracked JS heap. Tools like cgroup memory accounting (/sys/fs/cgroup/memory.current on cgroups v2) or your orchestrator's own metrics (kubectl top pod, cAdvisor, Prometheus node/cgroup exporters) give you the ground truth number that will actually trigger an OOM kill.
Step 2: Detect Memory Leaks Using Heap Dumps
A heap snapshot is a full point-in-time dump of every live object in the V8 heap, along with what's referencing it. Comparing two snapshots taken minutes apart under load is the most reliable way to confirm and locate a leak.
Generating a heap snapshot programmatically
The built-in node:v8 module can write a snapshot to disk without any third-party dependency:
import { writeHeapSnapshot } from 'node:v8';

// Somewhere reachable — an admin route, a signal handler, a debug script
const filename = writeHeapSnapshot();
console.log(`Heap snapshot written to ${filename}`);
A few things worth knowing before you run this in production:
- Generating a snapshot is a synchronous, blocking operation — it pauses the event loop for a duration proportional to heap size, so avoid triggering it on a hot path in a live production instance without warning.
- Snapshotting temporarily needs roughly twice the current heap size in memory, which can itself trigger an OOM kill on a tightly constrained container. Snapshot from a container with headroom, or from a staging replica under similar load.
- A snapshot is scoped to a single V8 isolate; if you're using worker threads, you need a separate snapshot per thread to see their respective heaps.
The three-snapshot workflow
Rather than staring at one snapshot, use a comparison protocol:
- Baseline — take a snapshot right after startup or a warm-up period.
- Load — repeat the suspected leaking action deliberately (hit the endpoint, process the job type, open/close the connection) a known number of times, say 10.
- Target — take a second snapshot.
- Reverse — undo or let the action naturally complete, force a GC if you're testing locally with
--expose-gcandglobal.gc(), then take a final snapshot.
Load both the baseline and target snapshots into Chrome DevTools' Memory panel, switch to "Comparison" view, and sort by "Delta." Objects whose retained count keeps growing across every cycle — regardless of GC — are your leak candidates. Click into one, inspect its retainer chain (the path of references keeping it alive), and that chain usually points straight at the offending code: an event listener that's never removed, a Map or array used as a cache with no eviction policy, a closure captured in a long-lived timer, or a detached reference kept alive from a module-level variable.
Common Node.js leak patterns to check for
- Unbounded caches — an in-memory
Mapor object used as a cache with no TTL or max-size eviction. - Event emitter listeners added on every request but never removed (
.on()without a matching.off()/.removeListener()). - Closures over large objects captured by long-lived
setInterval/setTimeoutcallbacks that never get cleared. - Global arrays/queues that push but never shift/pop under backpressure.
- Stale references in module-level singletons in long-running processes, which is a much bigger risk in Node than in short-lived scripts since the process may run for weeks.
Step 3: Adjust V8 Flags for Container Runtimes
Once you understand where memory is actually going, the flags below let you shape V8's behavior to fit your container's real memory budget.
--max-old-space-size
This is the primary lever — it caps the maximum size of the Old Space, in megabytes:
node --max-old-space-size=1536 server.js
Or via environment variable, which is often more convenient for Docker/Kubernetes since you don't need to modify the entrypoint:
NODE_OPTIONS="--max-old-space-size=1536" node server.js
The rule of thumb: set this below your container's hard memory limit, not equal to it. V8's total footprint includes more than Old Space — New Space, code space, and native/off-heap memory (Buffers, native addon allocations) all add on top. A common starting point is roughly 75–80% of the container's memory limit dedicated to --max-old-space-size, leaving the rest for New Space, native memory, and the Node.js runtime itself — then adjust based on what you actually observe in profiling.
--max-old-space-size-percentage
Newer versions of Node.js support expressing the limit as a percentage of available system memory instead of a fixed number, which is useful when the same image runs across containers of different sizes:
node --max-old-space-size-percentage=75 server.js
This flag takes precedence over --max-old-space-size when both are set, and it's particularly convenient in autoscaled environments where the container's memory allocation might change between deployments.
Node's built-in container awareness
It's worth knowing that Node.js has been container-aware since version 12: when no explicit heap flag is set, Node.js queries the cgroup memory limit itself and lets V8 select a default Old Space ceiling based on that boundary, rather than defaulting purely off host-level physical memory (which is what caused V8 to badly over-allocate in early container deployments). This means blindly setting --max-old-space-size on modern Node.js isn't always necessary — but it also means that if you do set it manually, you should base the value on the container's cgroup limit, not the host machine's total RAM, or you'll recreate the same mismatch problem manually.
--max-semi-space-size
This controls the size of each semi-space within New Space (the young generation). Increasing it can reduce the frequency of minor GC pauses for allocation-heavy workloads (e.g., high-throughput request handling that creates many short-lived objects), at the cost of a larger memory footprint:
node --max-semi-space-size=64 server.js
Only raise this if profiling shows frequent Scavenge pauses are actually a bottleneck — for most typical API services, the default is fine.
Diagnostic flags worth knowing
--trace-gc— logs every garbage collection event with timing and heap size before/after, useful for correlating GC pauses with latency spikes in your logs.--expose-gc— exposes aglobal.gc()function you can call manually during local leak-hunting sessions (never enable this in production; it lets any code force a full GC, which is a footgun for performance).node --help --v8-options— dumps every V8 flag available in your exact Node.js build, since flags and defaults change between versions.
Putting it together in a Dockerfile / Kubernetes manifest
A pragmatic pattern is to keep the memory limit and the V8 heap ceiling declared next to each other so they're never adjusted independently:
ENV NODE_OPTIONS="--max-old-space-size=1536"
resources:
  limits:
    memory: "2Gi"
  requests:
    memory: "1Gi"
Here, the container is allowed up to 2 GiB, and V8's Old Space is capped comfortably under that, leaving headroom for New Space, native memory, and any child processes. If you change the pod's memory limit, revisit the flag — they are not automatically kept in sync.
Putting the Workflow Together
- Instrument the process with
v8.getHeapStatistics()and container-level cgroup memory metrics side by side. - When memory trends upward without recovering after GC, capture baseline/target/final heap snapshots around the suspected code path.
- Compare snapshots in Chrome DevTools' Memory panel, follow retainer chains, and fix the actual reference leak in code — a bigger heap limit never fixes a leak, it only delays the crash.
- Once the code itself is healthy, size
--max-old-space-size(or--max-old-space-size-percentage) against your container's real memory limit, leaving margin for non-heap memory. - Re-test under realistic load and watch for OOM kills or
JavaScript heap out of memoryerrors before shipping the configuration.
Garbage collection tuning is not a substitute for fixing leaks — it's what keeps a healthy application's memory behavior predictable once it's running inside the hard boundaries a container imposes. Do the profiling work first; the flags are the last 10%, not the first.
Further Reading (Official Documentation)
- Understanding and Tuning Memory — Node.js Learn
- Node.js
v8module API reference - Node.js Command-Line Options reference
- Fix memory problems — Chrome DevTools documentation
- Resource Management for Pods and Containers — Kubernetes documentation
Related on TVerge Tech: Node.js Event Loop Microtasks: Tuning nextTick, setImmediate & Timers